The software factory
Specification in. Verified software out.
The INSPIRE Factory turns the knowledge graph into working code. It plans what is ready, builds every unit with an agent in its own sandbox, proves each claim of the specification with a test, and hands you one release to review. Agents write the code. Deterministic checks decide what merges.
The line
Five steps, from the graph to a pull request.
Units run in parallel, each in its own worktree. A unit that fails its checks goes back to a fresh agent; one that passes merges into the release. Nothing reaches your main branch without a person reviewing it.
Watch it run
The whole line in two minutes.
Scope a build, follow the agents, review the evidence. Jump to any chapter.
Plan
Execute
Review
The planner and run viewer are the real factory UI. Execution scenes use an illustrative sample project, Team Tasks.
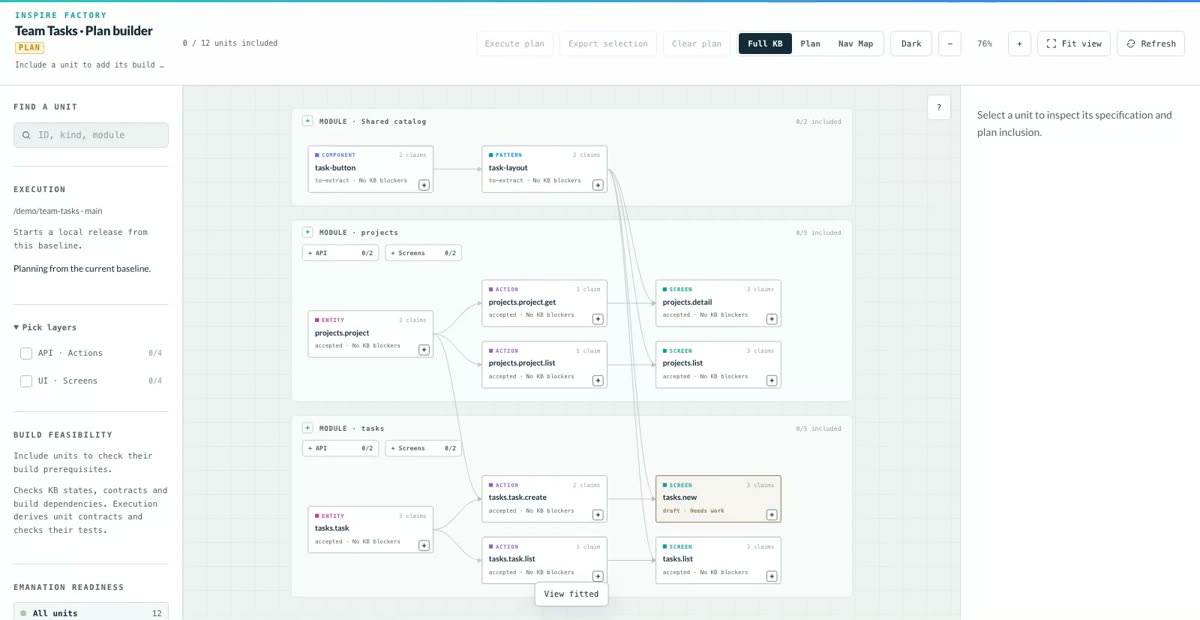
01 · Choose the build
Only what is ready, in the right order.
The planner reads the knowledge graph directly. It finds every unit by its typed extension under inspire_kb/01_spec/: entities, actions, screens, components, patterns, layouts, bundles and processes, and follows the relative Markdown links between them. It keeps the units whose specification is accepted and orders them by their dependencies. A unit whose tests already cite every current claim is skipped, so a rerun builds only what is new or what changed in the spec.
- Pick a module, a face, a layer or single units. Their dependencies are added to the plan.
- Entities, actions and module processes are built with the backend's profiles, screens with their face's. A process under a face's
_processes/, such as a token renewal, is that face's: it is built and tested there, with the face's profiles. - An entity that names a
datastore:other than the default gets its table and migration in that database, with that database's skill. A reference between two databases is kept in the application, never as a foreign key. - When one shared change, such as an edit to a stack skill's bindings, makes the same claims of many built units stale, they become a single update unit of up to 20: one agent, one setup, one pass of checks and one merge.
- Readiness blockers name the exact specification to fix.
- A cycle or an unready unit stops the run before anything is created.
- A project on an INSPIRE older than 0.17.0, with a knowledge base in the old layered layout, or with a wikilink left outside code, is refused. The message points to
/inspire:updateor/inspire:migrate. - After
/inspire:migrateconverts the links,bun run remapre-stamps every citation whose claim changed only in link syntax, so nothing already built is built again.
02 · Implement in isolation
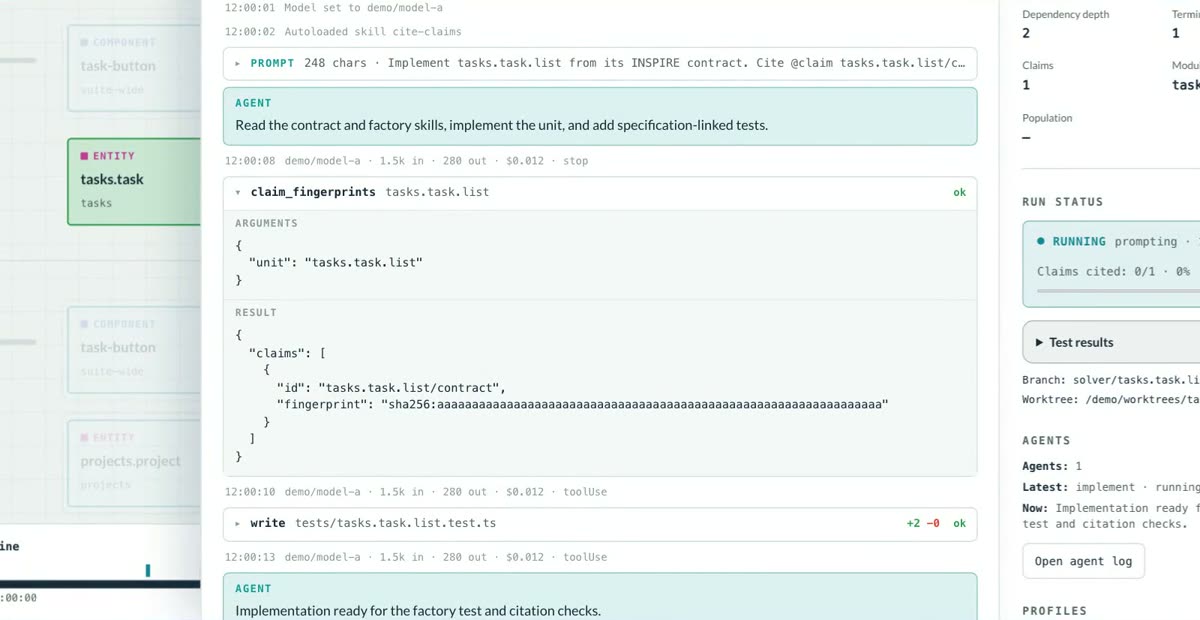
Every unit gets its own sandbox.
Each unit is built by an agent in its own git worktree. The agent runs in a container of your project's image, next to the unit's own services, such as an empty PostgreSQL. The agent receives the unit's contract, derived from the specification: every claim it must satisfy, each with an id and a fingerprint.
- Up to three units at a time by default, and only as many as fit in Docker's memory: each reserves its sandbox's memory plus its services'. A unit waits only for the units it depends on.
- Units share all the CPUs, so a unit running alone uses every one. At most two check commands (lint, typecheck, test suites) run at once across all units, and
check_concurrencychanges that. Under memory pressure the kernel stops unit containers first and the orchestrator last. - Agents load the factory's skills and the stack skills committed in your project, never user skills.
- An agent can hand read-only work to subagents, on its own model or on a cheaper one you list.
- The model credential stays in the orchestrator. The agents never see it.
- Every prompt, tool call and file write is kept as a transcript.
When the spec contradicts itself or the stack, covers no behaviour the agent needs, or leaves it unsure how to go on, the agent reports a spec problem instead of filling the gap: a title, the complaint and a proposed solution. spec_strictness decides what the report does:
A revision that leaves a unit without a contract, breaks a link or adds a validator error is undone and the unit stops, and a run commits at most spec_max_revisions of them, five by default. When a revision moves, every unit it affects derives its contract again.
03 · Verify tests and claims
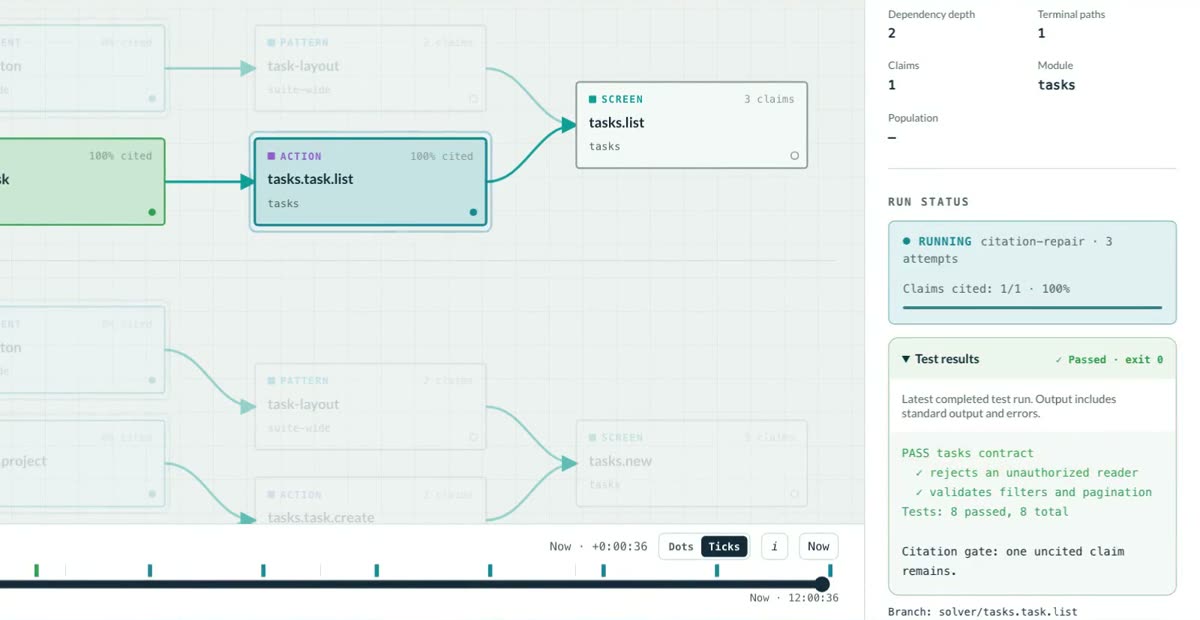
Green tests are not enough. Every claim needs its test.
A unit is done when every check you configured passes and every claim of its contract is cited by a test that asserts it. Checks run in phases: lint and typecheck, an optional AI reviewer that judges the change against your stack's conventions, then tests. A test check can run only the tests related to the files the unit changed; the whole suite runs once more on the release. The factory checks the citations itself, against the specification:
// @claim samples.sample.create/input/code/len sha256:5565d782…
test('rejects a code longer than the limit', …)A suite that only timed out runs once more. A red check, a review finding or a deviating citation goes to a fresh agent with no memory of the last attempt, a bounded number of times. The repair prompt keeps a long check output's end, where test runners sum up their failures, and the whole output is saved in the worktree for the agent to search. A unit that stays red keeps its worktree and blocks its dependents. Independent units continue.
04 · Merge and publish
One release. One reviewable pull request.
Verified units merge one at a time into a release branch, release/<date>-<id>. Before each merge the unit takes in what already landed and, if anything moved, runs its tests and citations again, so units built in parallel are tested together. That recheck runs outside the merge lock, so other units merge meanwhile.
- When units ran only their related tests, a release check runs every suite whole on the release. A suite that stays red after its repairs fails the run.
- When every unit succeeds, the factory pushes the release and opens a single PR. It never merges it.
- Run logs and transcripts are committed to the release.
- A failed or stopped run keeps its release and worktrees, and opens no PR.
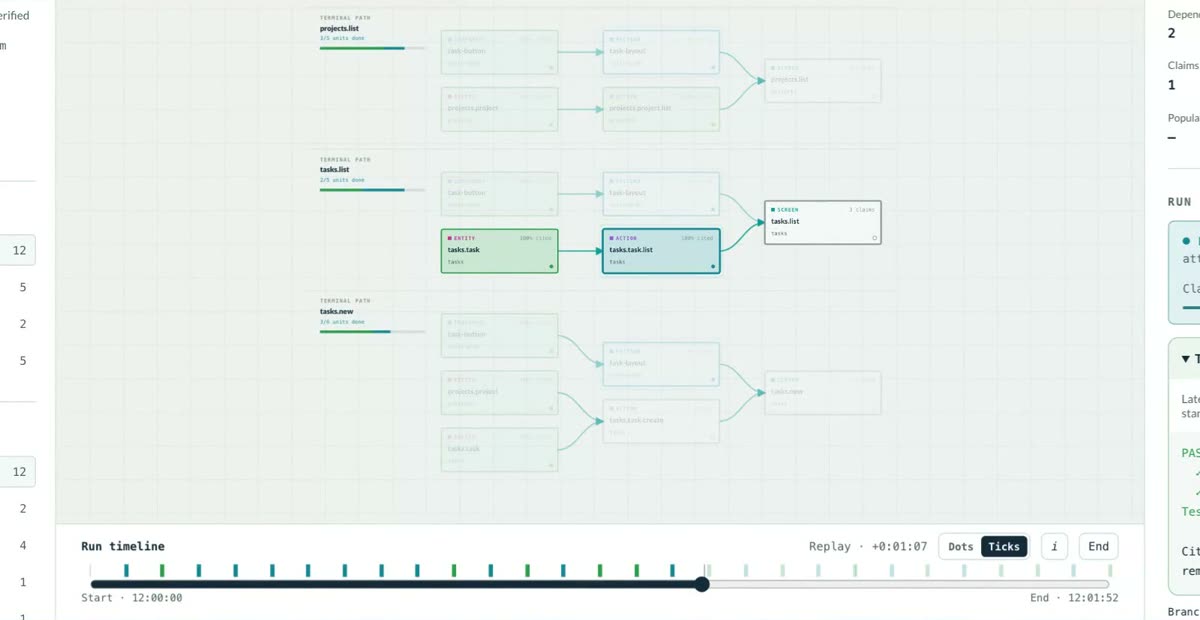
- The run viewer says when a run is starting and when it has ended, keeping the graph and stopping the clock. Every run ends with a summary, in the terminal and the viewer: passed, failed or stopped, the units in each outcome, the first line of each failure and the pull request or why none opened. A failed unit shows its error, cause first, and a unit stopped by another links to that unit.
05 · Analyze the evidence
Every run explains itself.
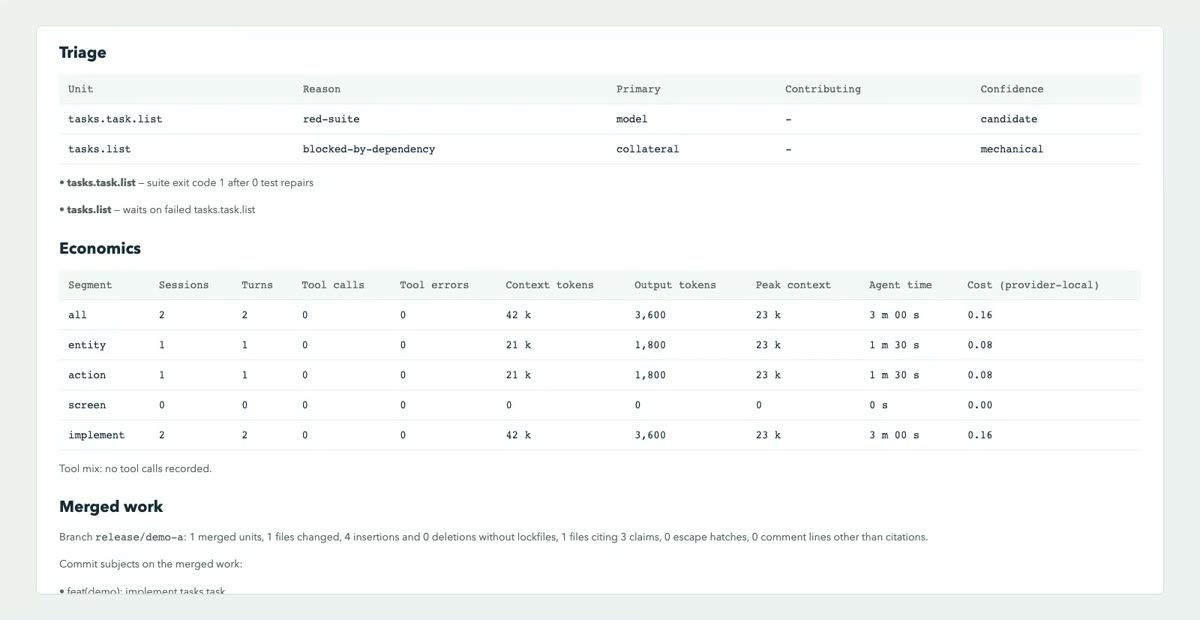
After a run, the analyzer reads the plan, every transcript and the merged history, and writes a report: what each unit delivered, how long each phase took, what it cost and, for every unit that did not complete, a reason and where the fault lies.
Runs of the same plan can be compared side by side, so models are judged only on the units each run built on its own merits.
Configure
One committed file.
.inspire/emanate.yml is the factory's only configuration. Its factory section holds the run settings. The rest says how every unit is set up and checked: the image it runs in, the services its tests reach, the setup command and the phases of checks. /inspire-config writes it from your stack and validates it with the factory's own reader.
factory:
  model: anthropic/claude-opus-5-5:high
  subagent_models: [anthropic/claude-haiku-5-5]
  sandbox: { memory: 1536m }
  concurrency: 3
  spec_strictness: strict
  base_branch: main
image:
  name: node:24-trixie
services:
  postgres: { image: postgres:18.6-trixie, memory: 512m, … }
env:
  DATABASE_URL: postgresql://…@postgres:5432/app
setup: cd source && npm ci
bash_timeout: 600
phases:
  - { name: quality, checks: [{ name: Lint, run: … }] }
  - { name: review,  checks: [{ review: … }] }
  - { name: tests,   checks: [{ name: API tests, run: …,
                                run_related: … {files} }] }
  - { name: claims,  checks: [{ claims: [source/apps/api/src] }] }
Any model, any language
Use the Claude subscription, or route every agent through a LiteLLM gateway, with each call tagged by run and agent kind. Every model name is checked before planning and before the sandbox starts, so a typo stops the run before it spends anything. Units run in your project's own image, so a new language needs no change to the factory.
A working baseline first
On an empty project, the factory starts from a matching template, react-nestjs-npm (Vitest, oxlint, oxfmt and tsgo) or react-fastapi-uv, or has an agent build a tested baseline before any unit begins.
Any test runner
Jest, Vitest, pytest, Go, Cargo: a check passes or fails by its exit code. bash_timeout raises the agents' 300-second limit on a shell command for slow checks. Unknown keys are refused, and secrets stay in .env, never in the file.
Inside your agent session
INSPIRE prepares the project. The factory builds it.
The factory runs on its own and needs no INSPIRE installation. Coding happens only in the factory. Your agent session prepares what the factory reads.
How every unit is built
inspire-code-<stack>
Stack skills hold one stack's conventions: layering, test conventions, forbidden patterns, review focus, build commands and the bindings a framework derives. A unit gets the skills whose stack is listed in your stack.md profiles. INSPIRE ships React, NestJS, Angular, iOS, Android and TypeScript, and you can add your own.
How the factory runs it
/inspire-config
init derives .inspire/emanate.yml from your stack and its skills. It asks only what they leave open, such as the image, the exact service tags and which commands block a unit, and it validates the result with the factory's reader. review checks an existing file without changing it.
The factory is only as good as the knowledge it reads.
That is why INSPIRE puts the human effort into the methodology and the knowledge graph, and leaves the rest of the work to the line. Built on proven primitives such as Vitacora.